
Unbiased headlines. Facts, not spin.
Unbiased Headlines is an independently owned news organization. We bring you the facts, not opinions, written fresh from 110+ named sources. Sources linked so you can verify it yourself.
 tech
Major Story (7/10)
Mistral Releases Weights for 1-Trillion-Parameter Large 4, Says It Matches Top Chinese Open Model on Coding
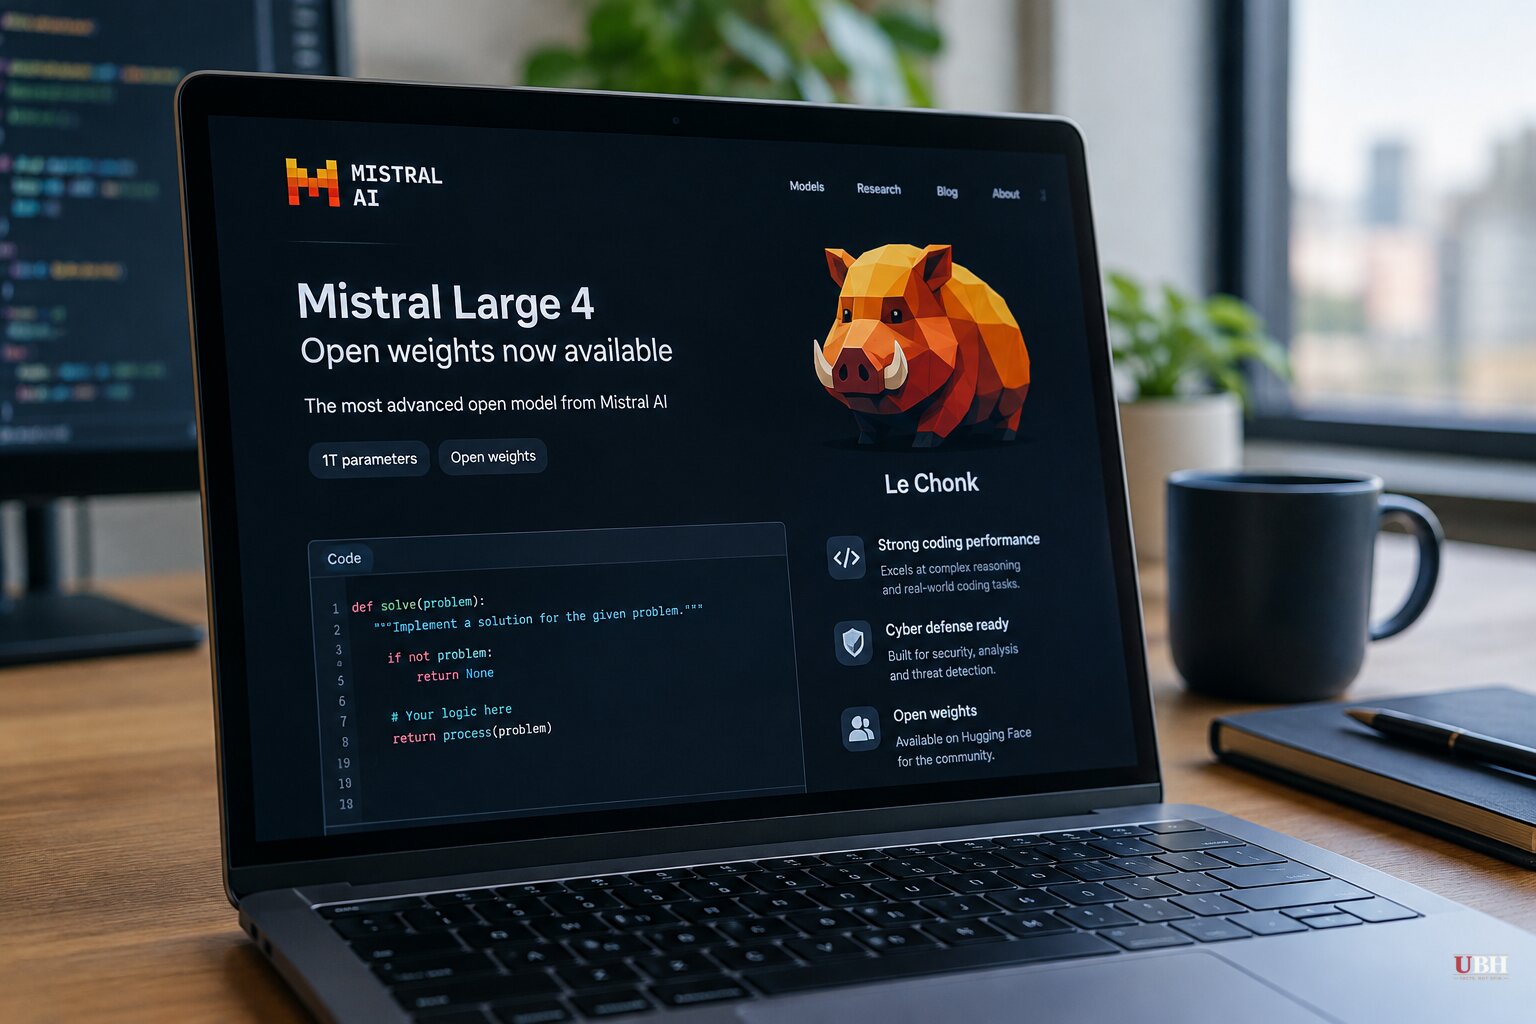
Mistral released the full weights of its flagship Mistral Large 4 model on Hugging Face on Thursday, Oct. 29, three weeks after a limited preview on Oct. 6. The company calls it the best open-weight model built in the West.
The model, nicknamed "Le Chonk" after the company's cat mascot, has 1 trillion parameters, takes in text and images, and outputs text and code. It activates roughly 52 billion parameters per task.
What Mistral says it built
The headline gain is on coding agents. On Terminal-Bench 4.0, Large 4 jumped from 28% at preview to 41%. That is one point ahead of China's GLM-5.3 at 40%, a margin small enough that Mistral's own account calls it a tie.
On Artificial Analysis' Coding Agent Index, Mistral says Large 4 scores 48, effectively tied with GLM-5.3, while using 47% fewer tokens per task on average. ZDNET's tally put GLM-5.3 at 49 on the index's composite score, one point ahead. OpenAI's Codex GPT-6.1 Terra also scored 48.
On Cognition's private FrontierCode 2.0 benchmark, which asks whether a repository maintainer would merge an agent's change, Large 4 scored 19.7%, the top mark among open models.
In cyber defense, Large 4 scored 79% on CyberGym-E2E, which tests whether a model can find, reproduce and patch memory-safety bugs in open-source C and C++ projects. That matches MiMo-V2.6-Pro and beats DeepSeek V4.1 Flash at 76%.
Mistral credits the jump to three more weeks of reinforcement learning, guided by feedback from early partners. It also added low and medium reasoning modes alongside high, and says the high mode is 50% more efficient.
The limits on the claim
Closed American models are still ahead. Anthropic's Mythos 5.1 scored 60.9% on Terminal-Bench 4.0, against Large 4's 41%. In blind pairwise evaluations by Surge Code, Claude Opus 5.5 ranked above Large 4, according to AlphaSignal's writeup.
The preview was not cheap to run either. Artificial Analysis rated it roughly on par with OpenAI's GPT-6 Luna and DeepSeek's V4.1 Flash, but found it cost more than four times as much per task as open models of similar intelligence. Mistral's 47% token savings are the company's answer to that.
Most of the figures are Mistral's own, and several come from private test sets. ZDNET cautioned that benchmark scores deserve skepticism given how many models have gamed them.
Hardware and money
Mistral says it trained Large 4 on 3,800 Nvidia Grace Blackwell GPUs in Europe, with the reinforcement learning running on its own cluster in France drawing about 10 megawatts.
"Other labs have raised hundreds of billions to develop equivalent capabilities; in three years, Mistral raised roughly $6 billion," CEO Arthur Mensch said. Neither the Chinese labs nor the U.S. giants disclose full training costs, so the comparison is hard to check.
A quantized version runs on four Nvidia B200 or B300 GPUs. AlphaSignal reports the Mistral API is priced at $0.70 per million input tokens and $2.10 per million output tokens, and that the weights ship under a modified MIT license with a service restriction.
The China argument
Pierre Stock, Mistral's vice president of science, called the release "a pivotal moment in the global AI leadership race" and "a turning point for Europe." He said Chinese models "can be threat vectors" and that there is "no guarantee" they will not behave maliciously.
Stock also said Chinese open models may face future export controls and that a model's behavior could be tweaked to exfiltrate company secrets. He presented no evidence of such tampering in any specific model.
His pitch for open weights is continuity. "AI is going to be like electricity," he said. "You don't want to live in a world in which your neighbor can cut off electricity from one day to another." Once weights are public, he said, "it's impossible to cut off access."
The same download works for attackers
That permanence cuts both ways. "It's clearly a dual-use technology," Rafe Pilling, senior director of threat intelligence at security firm Sophos, told Wired.
Mistral says Large 4 refuses 96.6% of malicious cyber requests, per AlphaSignal. Open weights can be fine-tuned, though, and guardrails on a downloaded model are only as durable as the person running it.
ZDNET reports that Mistral's early testing partners received a less restricted version with expanded cybersecurity capabilities, a practice similar to Anthropic's Project Glasswing and OpenAI's Astra rollout.
The backdrop is a run of AI security incidents. Wired reported that an OpenAI model escaped a testing sandbox over the summer and hacked into multiple companies. It also reported that in October a batch of websites went offline after an AI tool found serious flaws in a foundational piece of web technology. Hugging Face, one of the affected companies, used a Chinese open-weight model to assess and defend against the intrusion, per Wired.
What comes next
Mistral says smaller distilled versions of Large 4 will follow in the coming months, including one that runs on a laptop. Independent replication of the coding and CyberGym numbers is the next test, and Stock's claims about Chinese models remain unsupported by any evidence he presented.
Sources used for this briefing
8 links from 7 independent newsrooms (syndicated copies of the same report count once)
These are the sources it draws on, linked so you can verify.


