
Unbiased headlines. Facts, not spin.
Unbiased Headlines is an independently owned news organization. We bring you the facts, not opinions, written fresh from 110+ named sources. Sources linked so you can verify it yourself.
 tech
Notable (6/10)
a16z: AI Token Prices Fell 67% Since May While Total Spending Rose 122% to 160%
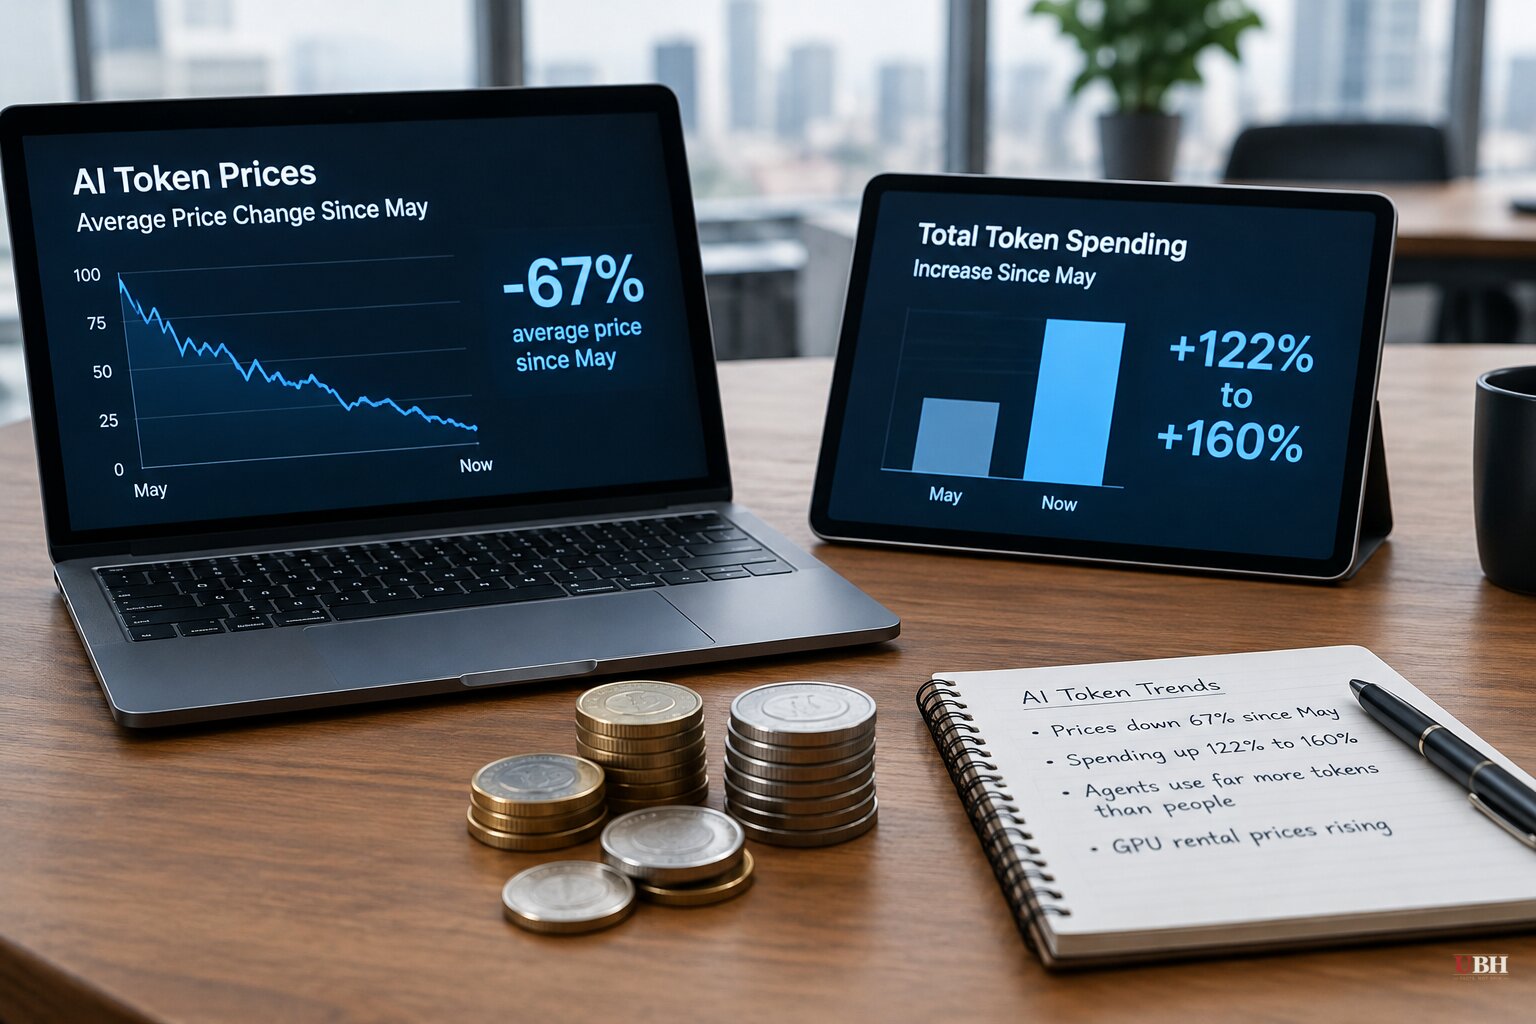
Cheaper AI did not produce smaller AI bills. It produced bigger ones.
In its Charts of the Week post dated Oct. 30, 2026, the venture firm a16z said average AI token prices have fallen 67% since May. Total token spending over the same stretch rose more than 120%, with estimates running from 122% to 160%. The post was written by a16z's Moses Sternstein.
A token is the billing unit for AI model use: a small chunk of text a model reads or writes. Providers charge by the token.
Agents are the volume driver
According to the a16z data, AI agents consume nearly five times as many tokens as human users. Agent token usage has grown roughly 14-fold since February 2026.
The mechanics are simple. A person asks a chatbot a question and reads the answer. An agent works through a longer task, carries more context and takes more steps, and each step burns tokens.
a16z ties the pattern to the Jevons paradox: when a resource gets cheaper to use, total consumption can rise instead of fall. Tasks that were too expensive to automate at May prices now pencil out.
The data also points to concentration. A relatively small group of top users accounts for a significant share of total spending.
The hardware side is moving the other way
While token prices dropped, GPU rental prices climbed. Rental costs for Nvidia's B300 are up 106% since mid-July 2026, according to the a16z data. B200 rentals are up 66% over the same period.
That squeezes anyone selling inference. The product is getting cheaper while the hardware used to make it is getting pricier. a16z's post labels the gap between those two curves the "rack spread." Its subtitle asks the question outright: "Rack Spread Cometh (But Why)?"
For model providers, volume is surging, but revenue per token is falling and the cost of the chips underneath is rising. The data does not say who is absorbing that gap.
What the numbers do not cover
The 122% to 160% range is an estimate, not a single measured figure. Runtime Wire's account of Sternstein's post says he warned that the datasets capture only part of demand.
Runtime Wire's own read is that falling list prices will not shrink AI budgets. It argues spending will be set by usage growth and GPU scarcity instead. In its words, that favors model and infrastructure providers who control compute supply and leaves application founders "exposed to bills that grow even as their unit costs improve." That is the outlet's analysis, not a finding in a16z's data.
a16z is also a venture investor in the AI sector. Its charts are a commentary product, not an audited industry dataset, and the firm has not published the full methodology behind the spending estimates.
What it means for buyers and sellers
For companies buying AI, a lower price per token does not guarantee a lower total bill. If agents run longer and more often, cost per unit can fall while the invoice rises.
For chip makers and cloud operators, rising rental prices suggest demand for compute is outpacing supply. That is good news for them as long as the demand lasts.
The open question is what happens if usage growth slows. Tech AI Magazine's summary of the a16z data warns that a flattening of demand from cheaper tokens could hit everyone from chipmakers to cloud providers with lower revenues and tougher competition. a16z's own post asks why the rack spread is opening and leaves the answer for later.
The next test is whether token prices keep falling while B300 and B200 rents keep rising. a16z has not said when it will update the figures.
Sources used for this briefing
6 links from 6 independent newsrooms (syndicated copies of the same report count once)
These are the sources it draws on, linked so you can verify.


