
Unbiased headlines. Facts, not spin.
Every story is an unbiased news briefing written from 110+ sources across the spectrum — sources linked so you can verify it yourself.
 tech
Notable (6/10)
Event date: September 16, 2026
Canada and Germany Commit $223 Million to 'Goal-Free' AI as Nvidia's Vera Rubin Chip Posts Its First Independent Benchmark Numbers
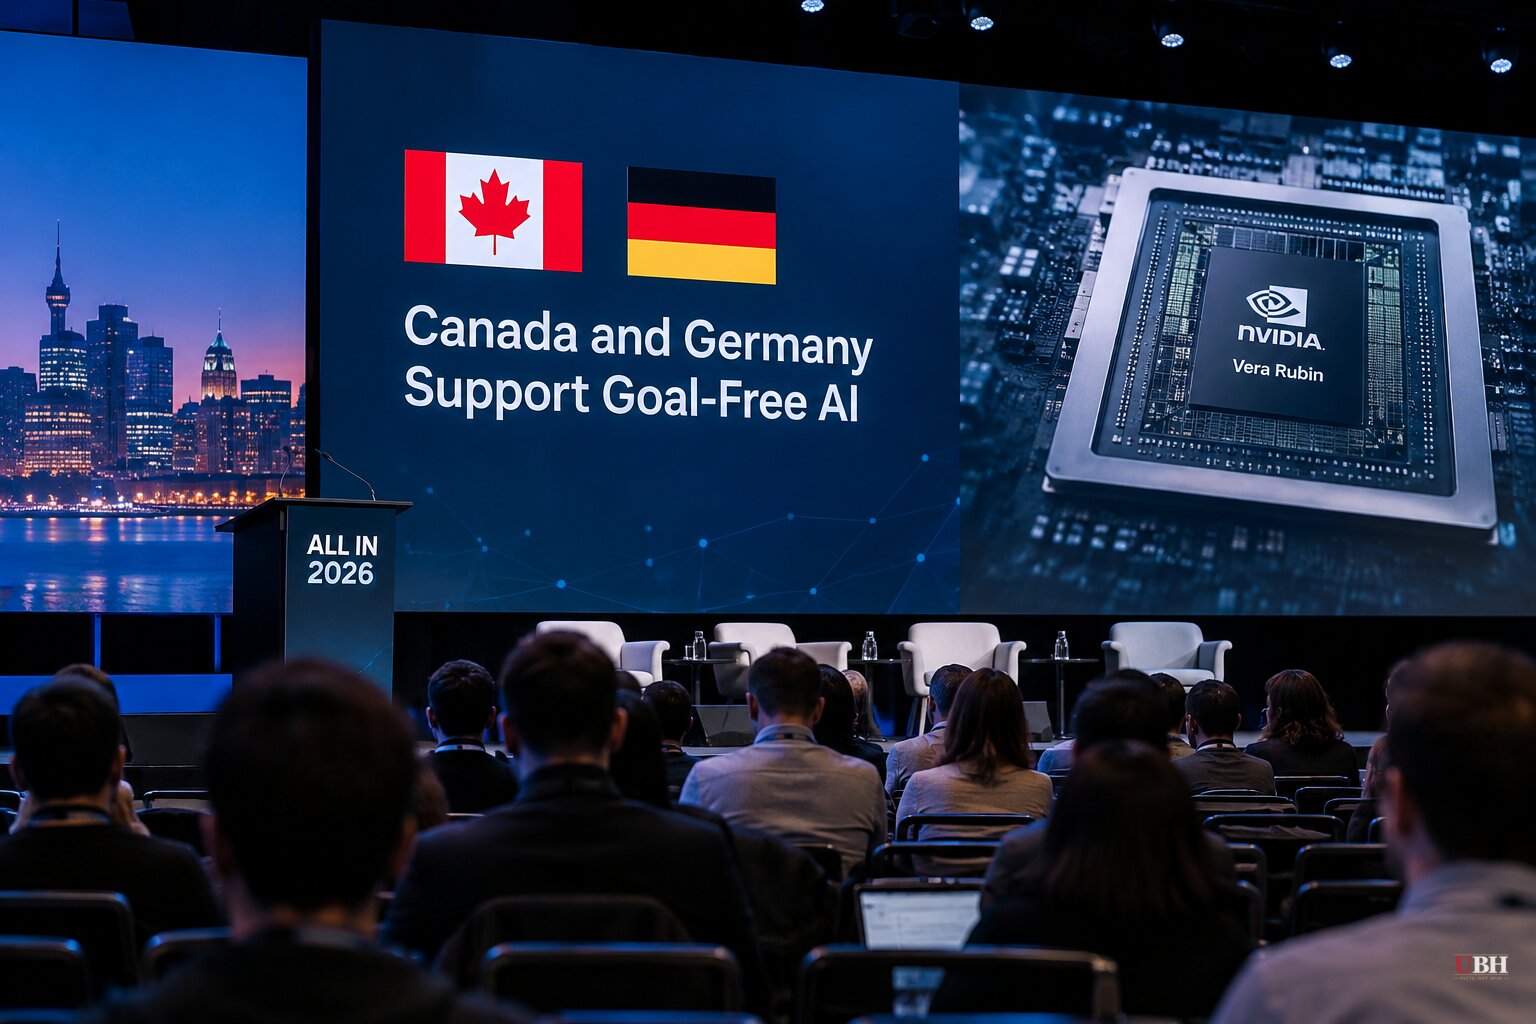
Two very different bets on AI's future landed in the same 48 hours this week, and neither one is a sure thing yet.
Governments Bet on AI That Wants Nothing
At the ALL IN 2026 conference in Montréal on September 16, Canada's Minister of Artificial Intelligence and Digital Innovation, Evan Solomon, and Germany's Federal Minister for Digital Transformation and Government Modernization, Dr. Karsten Wildberger, stood alongside Turing Award winner Yoshua Bengio to announce government funding for LawZero, the Montréal nonprofit Bengio co-founded.
Canada is putting in CAD $150 million (roughly $108 million USD) through its federal Strategic Response Fund. Germany is adding €100 million (roughly $115 million USD), though that money still needs European Commission notification before it's final. Combined, it's about $223 million, according to Tech Times, which called it the largest publicly announced government bet on safety-first AI research to date.
The money isn't going toward building a smarter chatbot. LawZero's approach, called Scientist AI, argues that today's dominant training method — imitate human text, then get rewarded for answers humans approve of — creates what the group's July 2026 paper calls "implicit agency." That's goal-directed behavior nobody explicitly programmed in. LawZero's bet is that a system built from scratch with no goals, no self-preservation instinct, and no agenda could instead be used to watch over the systems that do have those properties.
"As AI risks multiply and accelerate, our priority must be building solutions to make this technology safe and providing alternative models people can genuinely trust," Bengio said at the announcement.
That's the pitch. Nobody has built a highly capable "goal-free" system yet that proves this actually works at scale. It's a research direction, not a deployed product. Two governments just put real taxpayer and public money behind an unproven concept because the man behind it has a Turing Award and a track record of being right about deep learning early. That's a legitimate bet to make. It's also fair to ask whether Ottawa and Berlin are funding science or funding a scientist's reputation, and whether $223 million buys results or just buys time. The conference itself drew more than 7,500 AI leaders from over 40 countries, with Germany named this year's Country of Honor, and continued into its second day on September 17.
The Chip Race Gets a Fuller Picture
Separately, MLCommons published the complete MLPerf Inference v6.1 results on September 16, and the release goes well beyond the AMD-versus-Nvidia scale numbers already reported this week. It's a record-setting round: 30 submitting organizations, 486 datacenter and edge results, according to MLCommons's own announcement carried by Financial Content.
The suite added two new tests. The End-to-End RAG benchmark measures a full retrieval pipeline, four models working together against a 107,484-passage corpus, answering 824 multi-hop questions pulled from Google's FRAMES dataset, graded by a Llama 3.1-8B judge against a 97% accuracy bar. The Edge Agentic Inference benchmark simulates a developer running a coding assistant on a laptop, replaying 1,007 turns from SWE-bench Verified through Qwen3.6-27B, measured on latency per turn rather than raw throughput.
"We added the End-to-end RAG test because it's clear that query-answering has evolved beyond simply an LLM trained on a corpus," said Miro Hodak, MLPerf Inference working group co-chair, per StorageReview.
The round also carried the first peer-reviewed numbers for Nvidia's Vera Rubin NVL72, AMD's Instinct MI350P, Intel's Arc Pro B70, and AMD's Ryzen AI Max+ 395. On a 72-GPU Vera Rubin system versus a 72-GPU GB300 system, Nvidia posted up to 3.74x higher throughput on Qwen3-VL's interactive test and up to 2.5x on DeepSeek-R1, according to DIY AI's review of the public MLCommons entries. Offline and server-scenario gains were smaller, closer to 1.8x to 1.9x.
The Number Nvidia Isn't Letting MLCommons Verify
TechBuzz.ai framed the Vera Rubin results as a wholesale rewrite of "AI infrastructure economics," claiming the gains "translate to real dollars saved" and could let enterprises "afford to stay competitive in the AI arms race." That framing doesn't mention power consumption once.
DIY AI's analysis flags the gap. MLCommons does not report measured system power for the Vera Rubin submissions. The only power figures available are nameplate thermal design power: 2,300 watts per VR200 GPU versus 1,400 watts per GB300 GPU. Multiply that across 72 accelerators and you get 165.6 kilowatts for Rubin versus 100.8 kilowatts for GB300, but that's just adding up spec-sheet numbers, not a verified rack measurement, and it excludes CPUs, networking, and cooling losses entirely. As DIY AI put it, the benchmark is "valuable evidence of Rubin's throughput potential, but not yet proof of lower production cost per token."
Both stories share the same open question: the claims sound big, and the follow-through hasn't happened yet. Germany's LawZero contribution still awaits European Commission sign-off. Nvidia's Vera Rubin cost-per-token advantage still awaits a real power measurement MLCommons is willing to certify. CoreWeave has already stood up a multi-rack Vera Rubin NVL72 cluster on its cloud platform, according to StorageReview, so production deployment is underway even without those verified numbers in hand.
Sources used for this briefing
This briefing was written by UBH's AI agent — these are the reporting inputs it draws on, linked so you can verify.


